Image Generation Guide
The image generation API at KoboiLLM adheres to the OpenAI Images API specification, enabling seamless integration with any OpenAI or LiteLLM SDK. This guide explains endpoint calls, available parameters, multi-language code snippets, response schemas, and cost estimates across all supported image models (OpenAI gpt-image-*, Google Gemini, and Google Imagen).
Table of Contents
- Endpoints & Authentication
- Model and Price Reference
- Request Parameters
- Generating Images from Text
- Editing Existing Images
- Verify recorded charges
1. Endpoints & Authentication
Base URL:
https://api.koboillm.com/v1Append the endpoint path to the API origin, or configure this base URL in your SDK.
Primary Endpoints:
| Method | Path | Function |
|---|---|---|
POST | /v1/images/generations | Generate new images from text prompts |
POST | /v1/images/edits | Edit / modify existing images |
Authentication requires the header Authorization: Bearer sk-xxxxxx. Store your API key securely in an environment variable rather than hardcoding it into source files.
export LITELLM_API_KEY="sk-xxxxxx"2. Model and Price Reference
For current examples, choose an active model such as gpt-image-2 from Model List or API Quickstart. Other names below are historical examples and may not be available.
Availability: Imagen deployments are currently blocked and hidden from the new dashboard. Imagen examples below are reference material, not a currently usable option. Select an active image model from your account catalog.
⚠️ Pricing Disclaimer
Rates listed in this document are sourced from official vendor pricing pages (OpenAI and Google Cloud Vertex AI). Vendors may update rate cards at any time. Always verify live account billing on your dashboard at dashboard.koboillm.com.
2.1 — OpenAI Models
| Model | Endpoint Name | Billing Mode | Best Used For |
|---|---|---|---|
gpt-image-1-mini | gpt-image-1-mini | per-token | Thumbnails, high-volume generation, prototypes — lowest cost |
gpt-image-1.5 | openai/gpt-image-1.5 | per-token | General-purpose, balanced quality & price |
gpt-image-2 | openai/gpt-image-2 | per-token | Latest flagship, top prompt adherence, complex composition |
gpt-image-1 | openai/gpt-image-1 | per-token | Legacy version, same rate tier as gpt-image-1-mini |
chatgpt-image-latest | openai/chatgpt-image-latest | per-token | ”ChatGPT-style” reasoning image model — highest tier, ~3× gpt-image-1.5 |
dall-e-3 | openai/dall-e-3 | flat per-image | Legacy DALL·E 3 model |
dall-e-2 | dall-e-2 | flat per-image | Legacy DALL·E 2 model |
2.2 — Google Gemini Models (Token-based)
| Model | Endpoint Name | Best Used For |
|---|---|---|
gemini-2.5-flash-image | gemini/gemini-2.5-flash-image or vertex_ai/gemini-2.5-flash-image | Fast & affordable multimodal image generation — recommended Gemini |
gemini-3.1-flash-image | gemini/gemini-3.1-flash-image or vertex_ai/gemini-3.1-flash-image | Nano Banana 2 image generation |
gemini-3-pro-image | gemini/gemini-3-pro-image or vertex_ai/gemini-3-pro-image | Nano Banana Pro, highest fidelity in Gemini family |
2.3 — Google Imagen Models (Flat-fee per image)
| Model | Endpoint Name | Flat Rate per Image | Best Used For |
|---|---|---|---|
imagen-3.0-fast-generate-001 | vertex_ai/imagen-3.0-fast-generate-001 | $0.02 | Imagen 3.0 speed-optimized |
imagen-4.0-fast-generate-001 | vertex_ai/imagen-4.0-fast-generate-001 | $0.02 | Imagen 4.0 speed-optimized |
imagen-3.0-generate-001 | vertex_ai/imagen-3.0-generate-001 | $0.04 | Imagen 3.0 standard |
imagen-4.0-generate-001 | vertex_ai/imagen-4.0-generate-001 | $0.04 | Imagen 4.0 standard |
imagen-4.0-ultra-generate-001 | vertex_ai/imagen-4.0-ultra-generate-001 | $0.06 | Imagen 4.0 ultra — highest visual quality |
3. Request Parameters
Gemini 3.1 Flash Image and Flash-Lite Image ignore quality; it does not select a higher resolution. Omit it for these models and use supported native image options if needed. Other unsupported parameters can still be rejected.
| Parameter | Type | Allowed Values | Effect |
|---|---|---|---|
model | string | any model ID | Determines pricing tier and backend route |
prompt | string | free text | Tokenized as text_input |
size | string | 1024x1024, 1024x1536, 1536x1024, auto | Resolution. Influences output token count (and total cost). |
quality | string | low, medium, high, auto | Influences output token count. High quality uses ~15× more tokens than low (OpenAI only). |
n | integer | 1–10 | Image count. Cost scales linearly with n. |
response_format | string | Omit or use b64_json | GPT Image 2 and Gemini image models return b64_json even when a client sends url; no hosted image URL is created. |
4. Generate Images from Text
4.1 — cURL Example
curl -X POST https://api.koboillm.com/v1/images/generations \ -H "Authorization: Bearer sk-xxxxxx" \ -H "Content-Type: application/json" \ -d '{ "model": "gpt-image-2", "prompt": "Majestic dragon soaring over mist-covered mountains at sunset", "size": "1024x1024", "quality": "high", "n": 1 }'4.2 — Python (OpenAI SDK Example)
from openai import OpenAI
client = OpenAI(    base_url="https://api.koboillm.com/v1",    api_key="sk-xxxxxx",)
response = client.images.generate(    model="gpt-image-2",    prompt="Majestic dragon soaring over mist-covered mountains at sunset",    size="1024x1024",    quality="high",    n=1,)
import base64from pathlib import Path
Path("generated.png").write_bytes(base64.b64decode(response.data[0].b64_json))
5. Editing Existing Images
Use /v1/images/edits for image-to-image workflows, inpainting, and variations.
curl -X POST https://api.koboillm.com/v1/images/edits \ -H "Authorization: Bearer sk-xxxxxx" \ -F "model=gpt-image-2" \ -F "image=@input.png" \ -F "prompt=Change the sky color to deep purple sunset" \ -F "size=1024x1024" \ -F "quality=high"Verify recorded charges
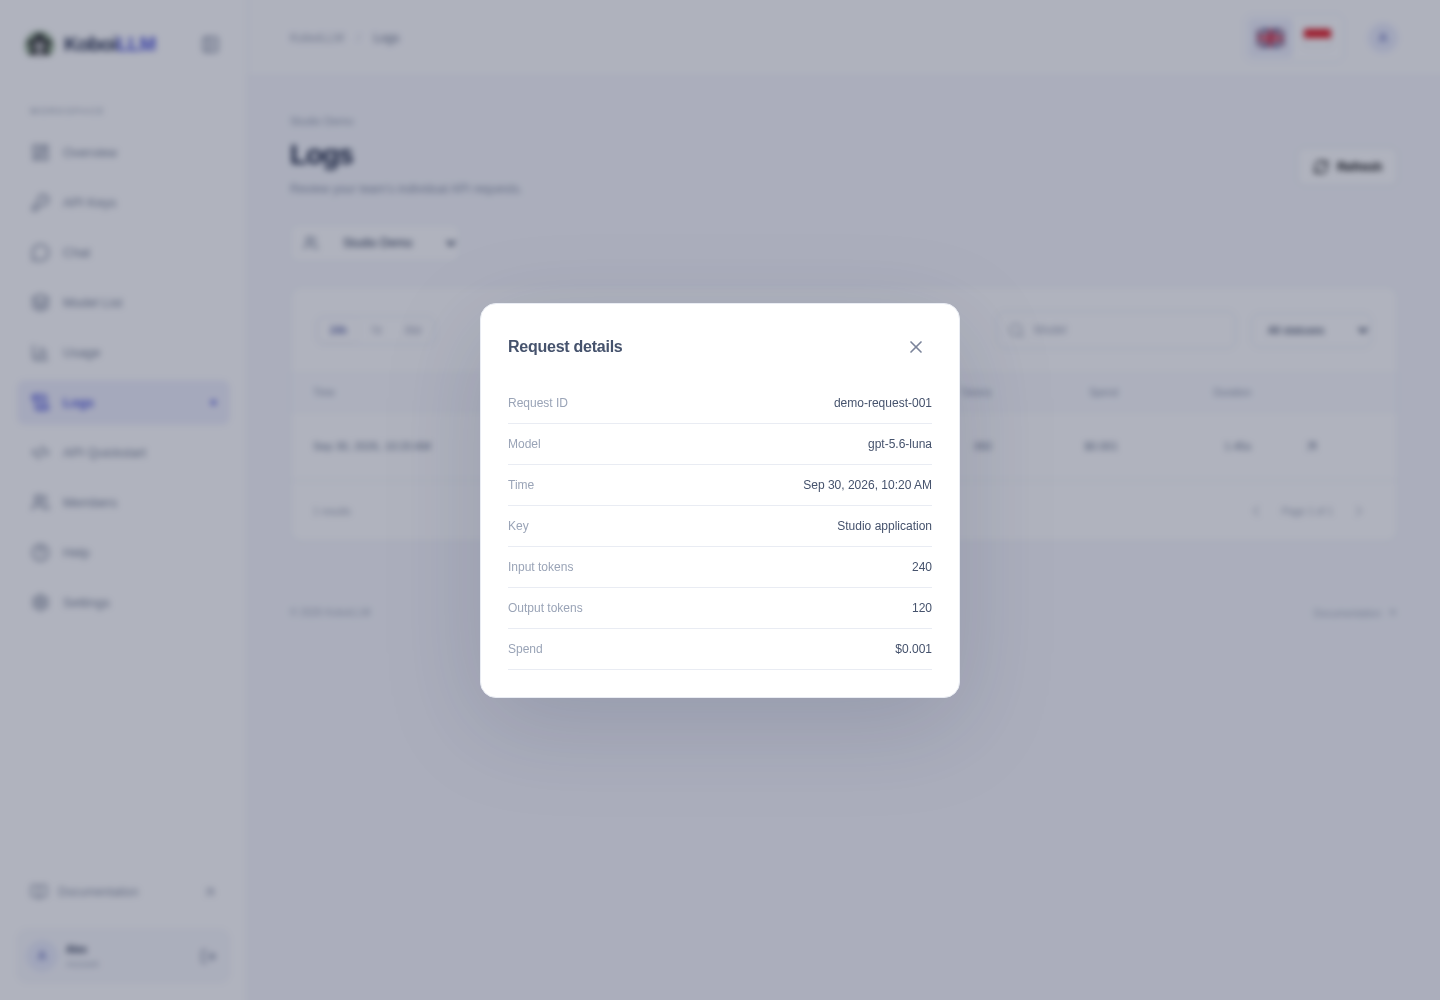
Sign in with your account email and password at Logs, select your team, filter by model/time, and choose View details. It shows Request ID, input/output tokens, and spend. The dashboard does not expose raw provider usage objects or prompt/response content. Image, cache, and tier rates can require more than the displayed token totals; provider estimates are not your final charge. Contact support with the Request ID for a discrepancy. A provider response ID is not necessarily the same ID shown in Logs.